POLYU SCHOOL OF DESIGN / SD2112 / WEEK 08
Humanizing AI.
Research. Relationships. Product responsibility.
POLYU SCHOOL OF DESIGN / SD2112 / WEEK 08
Humanizing AI.
Research. Relationships. Product responsibility.
0-10 / FROM WEEK 7 TO WEEK 8
Your concept is a starting claim.
Keep your existing team, product idea and image in view.
What does the AI do during use? What does the person still decide?
Today: research -> product decision -> a revised scope and a test.
Work in team notes; later, each person submits one different paper in ClassPoint.
SD2112 · AI IN DESIGN · WEEK 08
02
NEWS / 15 OCTOBER 2026 / OPTIONAL TWO-MINUTE OPENER
Directing an AI-generated scene
Kling 4.0: up to 30 seconds, 15 reference assets and 10 keyframes.
Vendor report, not independent evidence of reliable continuity.
What can you direct? What would you still need to test?
SD2112 · AI IN DESIGN · WEEK 08
03
10-30 / MEDIATION RECAP
Technology shapes the relation.
Ihde, Technology and the Lifeworld (1990); Verbeek, Beyond Interaction (2015). Same schema as Week 5.
SD2112 · AI IN DESIGN · WEEK 08
04
MEDIATION / ALTERITY
An apparent other is still a design relation.
Original teaching diagram after Ihde (1990). Quasi-other describes experience, not proof of a mind.
SD2112 · AI IN DESIGN · WEEK 08
05
DESIGN ANALYSIS / NOT A STUDY RESULT
A cue can become a promise.
Try: a name, a warm voice, "I remember", or "I am always here". What capability might each imply?
SD2112 · AI IN DESIGN · WEEK 08
06
OPTIONAL / PERSONAL EXPERIENCE / YES OR NO
Have you ever shared a deep secret with a chatbot that you would not tell a human?
A
Yes
B
No
Optional: you may skip. Do not share the secret.
Responses may identify you; this is not an anonymous poll.
SD2112 · AI IN DESIGN · WEEK 08
07
OPTIONAL / IF YOU ANSWERED YES / SHORT ANSWER
If yes, what made it easier to tell the chatbot?
Responses may identify you. Optional: you may skip.
Explain why, not the secret. No names or transcripts.
SD2112 · AI IN DESIGN · WEEK 08
08
THE HIDDEN DECISION / MACHINE A + B
Effortless for whom?
DATA
What disappears?
A conversation may become stored data. What is needed, retained or reused?
MODEL
What gets rewarded?
A pleasing answer, a truthful answer and a useful challenge are not identical.
INTERFACE
What seems certain?
A fluent answer can hide uncertainty, retrieval gaps and limits of the task.
SD2112 · AI IN DESIGN · WEEK 08
09
AGENCY / CALIBRATED TRUST
Can the person disagree and act?
BEFORE
Know the boundary.
What does the system do? What evidence and data does it lack?
DURING
Question the answer.
Compare, correct, override or ask for a source before the decision matters.
AFTER
Leave or recover.
Keep an exit, a human route and a way to repair the consequences.
SD2112 · AI IN DESIGN · WEEK 08
10
30-65 / READ THE CLAIM BEFORE THE HEADLINE
A paper is a bounded claim.
WHO + WHAT
People and system.
Who took part? What system and task were tested?
AGAINST WHAT
A comparison.
Compared with what? Random assignment or observation?
MEASURED HOW
Outcome and time.
A rating, a choice, an action or a symptom? For how long?
SD2112 · AI IN DESIGN · WEEK 08
11
01 / PERCEPTION + CHOICE
Seeming care.
Choosing a source.
A response rating is not a relationship or a treatment.
SD2112 · AI IN DESIGN · WEEK 08
12
THE STUDY / PERCEPTION + CHOICE / R1
Can a reply sound like good therapy?
WHAT THEY DID
830 US adults read 18 fictional couple-therapy situations. For each situation, they were randomly shown a selected reply written by ChatGPT-4 or by one of 13 experienced therapists; they were not receiving therapy.
WHAT THEY COMPARED
The source of the reply changed: selected AI response versus selected expert response to the same situation.
ILLUSTRATIVE EXAMPLE / NOT STUDY WORDING
One partner feels unheard after an argument. Read a possible therapist-style reply. Does it sound caring and understanding?
WHAT THEY MEASURED
Readers rated five qualities on 1-7 scales, including caring and understanding. They also guessed whether the writer was AI or human.
SD2112 · AI IN DESIGN · WEEK 08
13
THE RESULT / PERCEPTION + CHOICE / R1
A caring reply is not treatment.
READERS
830 US panel participants
MATERIAL
18 couple-therapy scenarios
COMPARISON
Selected ChatGPT-4 / expert replies
WHAT THEY FOUND
Selected AI replies received higher overall ratings for therapeutic qualities. Readers identified the author only slightly better than chance.
WHAT IT DOES NOT SHOW
These are ratings of written replies, not evidence that patients recovered. Replies were selected, and the AI replies were longer.
FOR YOUR DESIGN
What would justify calling your product therapy?
Original method illustration; not measured data.
SD2112 · AI IN DESIGN · WEEK 08
14
THE STUDY / PERCEPTION + CHOICE / R2
Does knowing the author change the rating?
WHAT THEY DID
140 people rated AI and human replies to ten everyday emotional problems, initially believing all replies were human. Six months later, 111 returned and rated the same replies again, now labelled with their real source.
WHAT THEY COMPARED
Compare source-concealed ratings with source-labelled ratings six months later. Also compare labelled human and AI replies.
ADAPTED FROM THE STUDY
A person feels unproductive and struggles to carry out plans. Readers judged advice from ChatGPT and a human psychology student.
WHAT THEY MEASURED
Readers used 1-5 ratings: authenticity (does it feel genuine?), professionalism, and practicality (is the advice usable?). Ratings were compared across assessments.
SD2112 · AI IN DESIGN · WEEK 08
15
THE RESULT / PERCEPTION + CHOICE / R2
Human replies felt more genuine.
INITIAL / SOURCE CONCEALED
140 respondents
SIX MONTHS LATER / SOURCE DISCLOSED
111 returned; same replies
OUTCOME
Three response ratings
WHAT THEY FOUND
Source-labelled human replies felt more authentic. Human ratings rose across assessments; AI ratings changed little.
WHAT IT DOES NOT SHOW
Six months passed and some did not return. We cannot isolate the label. No clear difference does not prove equal quality.
FOR YOUR DESIGN
What should disclosure help someone decide?
Original method illustration; not measured data.
SD2112 · AI IN DESIGN · WEEK 08
16
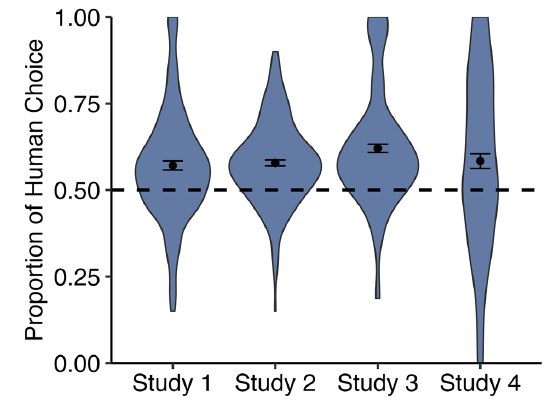
THE STUDY / PERCEPTION + CHOICE / R8
Which source would you choose for support?
WHAT THEY DID
Across four studies, 691 people repeatedly chose a human or AI reply. They read the chosen replies and rated them. Later studies used participants' own situations.
WHAT THEY COMPARED
Two separate outcomes: how often people chose a human source, and how they rated the replies they received after choosing.
ILLUSTRATIVE EXAMPLE / NOT STUDY WORDING
After a disappointing project critique, choose HUMAN or AI for support. Then read the reply and rate how understood it makes you feel.
WHAT THEY MEASURED
Researchers counted human versus AI choices. Readers used 1-7 ratings for empathy, comfort, feeling cared for and feeling heard.
SD2112 · AI IN DESIGN · WEEK 08
17
THE RESULT / PERCEPTION + CHOICE / R8
People chose humans but rated AI higher.
WHAT THEY FOUND
About 57-62% of choices went to humans, but AI replies generally rated higher for empathy and feeling heard.
WHAT IT DOES NOT SHOW
Sources were chosen, not randomly assigned. Brief tasks, not established relationships or clinical benefit.
FOR YOUR DESIGN
Should users choose their source?
Wenger et al. (2026), Fig. 1; published PDF p.5.
Cropped plot; CC BY 4.0. Dashed line = equal choice.
SD2112 · AI IN DESIGN · WEEK 08
18
02 / BENEFITS + THEIR HORIZON
Relief now.
Action outside the app.
Different outcomes need different evidence.
SD2112 · AI IN DESIGN · WEEK 08
19
THE STUDY / BENEFITS / IMMEDIATE RELIEF / R6
Does the relief last until the next day?
WHAT THEY DID
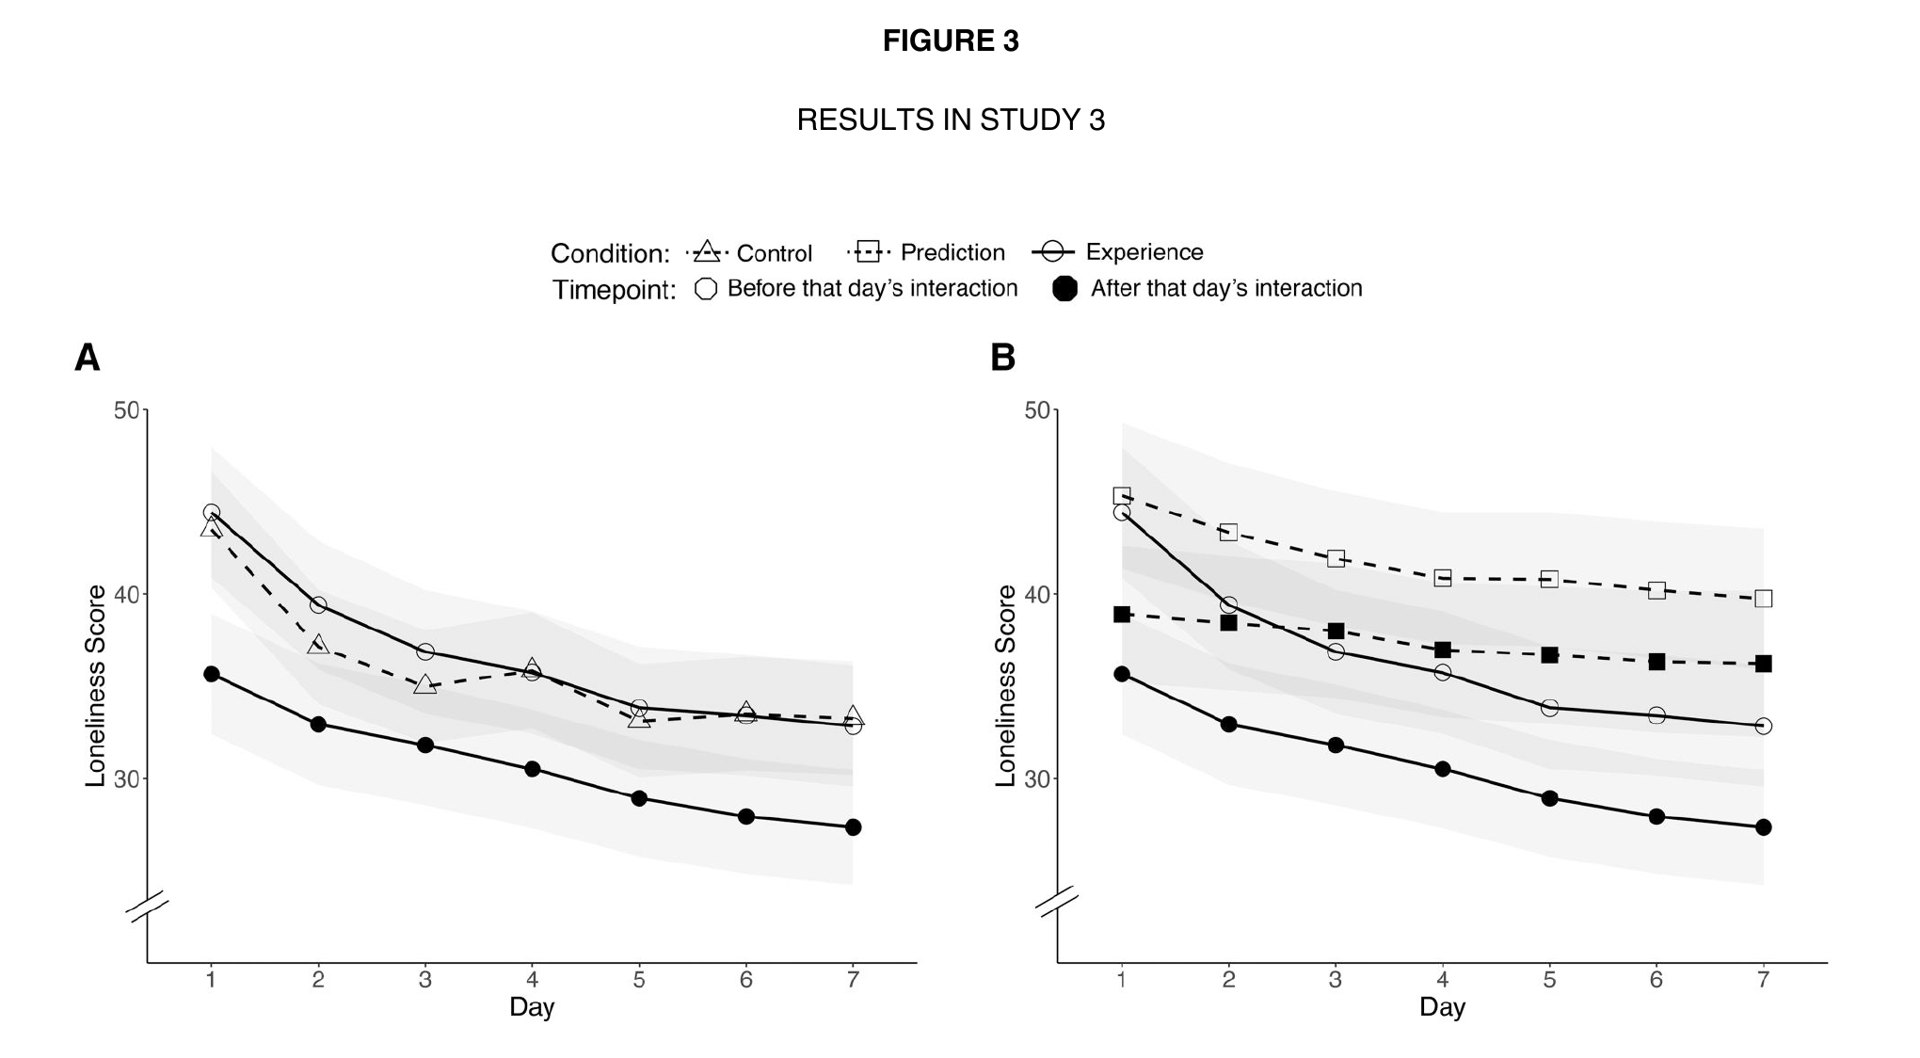
In a seven-day study, one group chatted with the GPT-4 companion Jessie for 15 minutes daily. A control group only completed daily loneliness questions; the main analysis used people who finished all seven days.
WHAT THEY COMPARED
Compare loneliness just before versus just after each chat, then compare the next day's before-chat score with the no-chat control.
ADAPTED FROM THE STUDY
Loneliness questions -> 15-minute chat -> the same questions. Repeat tomorrow. Feeling better after chat is different from feeling less lonely before tomorrow's chat.
WHAT THEY MEASURED
People rated current loneliness on a three-item UCLA questionnaire, including feeling left out. Chat users answered before and after; controls once daily.
SD2112 · AI IN DESIGN · WEEK 08
20
THE RESULT / BENEFITS / IMMEDIATE RELIEF / R6
Relief now is not lasting improvement.
WHAT THEY FOUND
Loneliness fell immediately after daily chats. Before-chat scores were not significantly lower than control scores on any day.
WHAT IT DOES NOT SHOW
No demonstrated between-session improvement. Seven days, unequal dropout and no equally time-consuming control; not clinical treatment.
FOR YOUR DESIGN
Measure relief, persistence, or both?
De Freitas et al., Fig. 3 A+B, final PDF p.13.
Open = before / filled = after; bands = 95% CIs.
SD2112 · AI IN DESIGN · WEEK 08
21
READ THE FIGURE / R6
Look between the sessions.
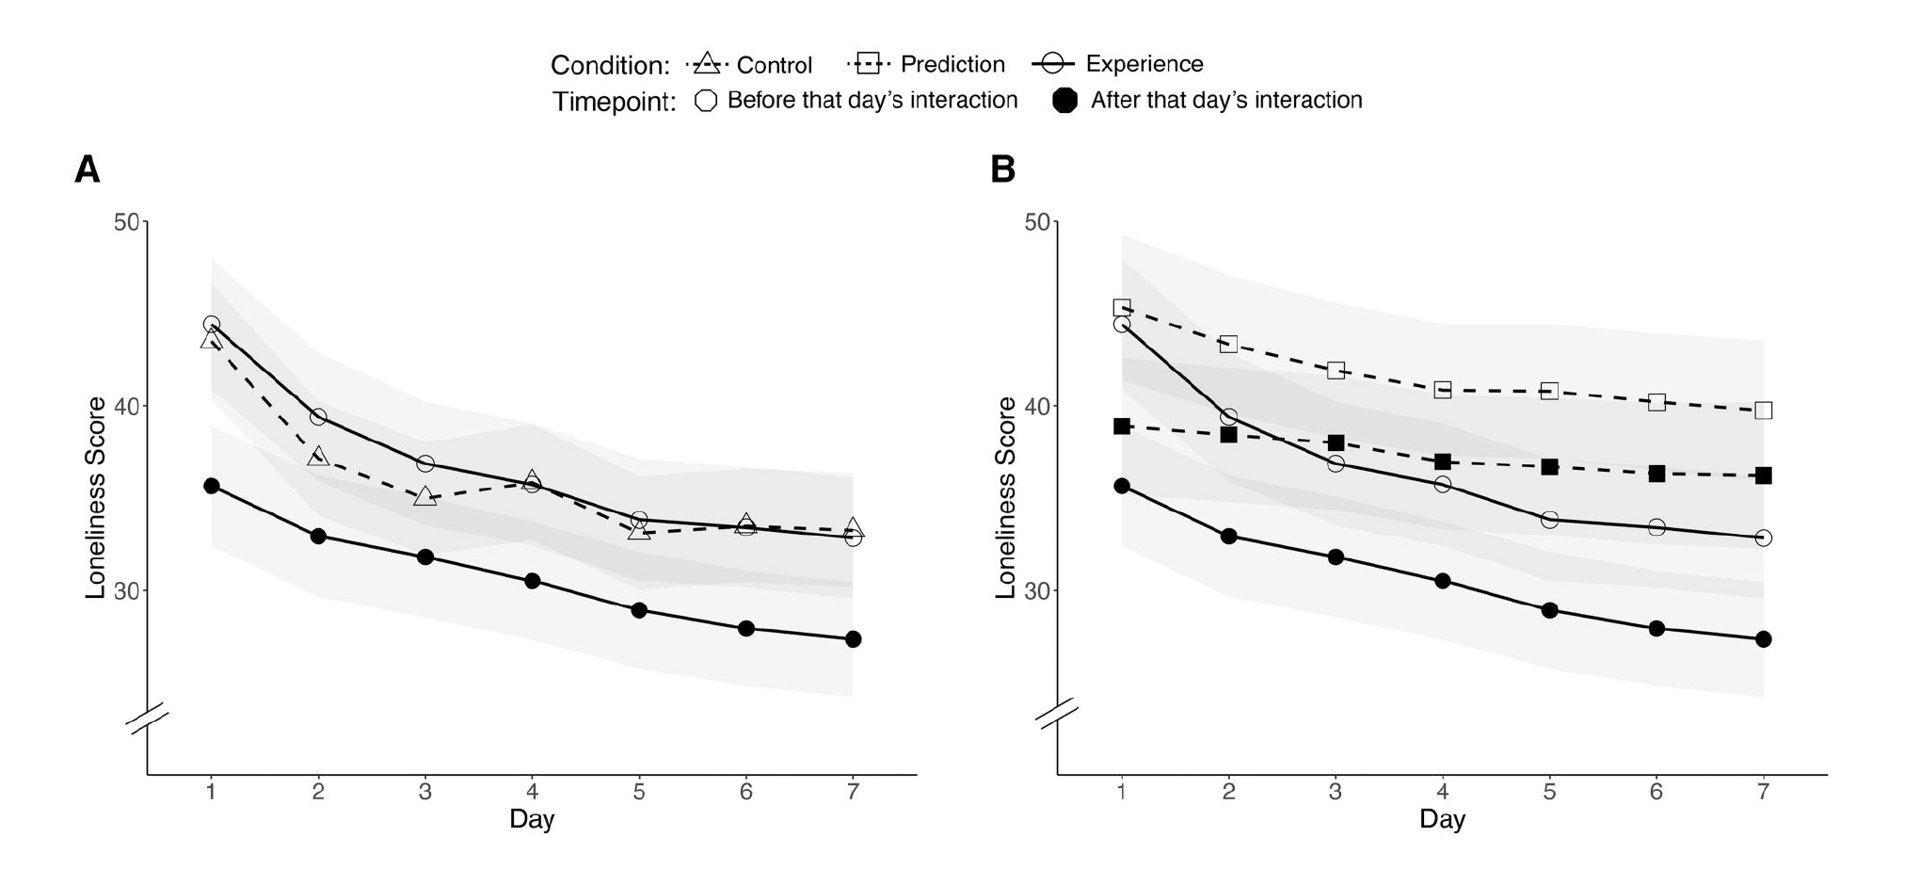
De Freitas et al., Fig. 3 A+B, PDF p.13. Open = before, filled = after; 95% CIs; broken axes.
SD2112 · AI IN DESIGN · WEEK 08
22
THE STUDY / BENEFITS / HUMAN ACTION / R7
Can rehearsal help start a conversation?
WHAT THEY DID
Adults named a difficult conversation. Random assignment: prepare with GPT-4o-mini for 6-12 minutes, or ask it three factual questions. Next week, 1,371 returned to report what happened.
WHAT THEY COMPARED
AI preparation for a personally relevant conversation versus an unrelated AI chat, not versus a human rehearsal partner.
ADAPTED FROM THE STUDY
One source-reported conversation: asking a boss for a raise. Preparation could include trying out what to say and anticipating the other person's reaction.
WHAT THEY MEASURED
Next week: did you have the conversation, yes or no? Participants also rated expected quality after preparation and reported quality after conversations.
SD2112 · AI IN DESIGN · WEEK 08
23
THE RESULT / BENEFITS / HUMAN ACTION / R7
Rehearsal can lead outside the app.
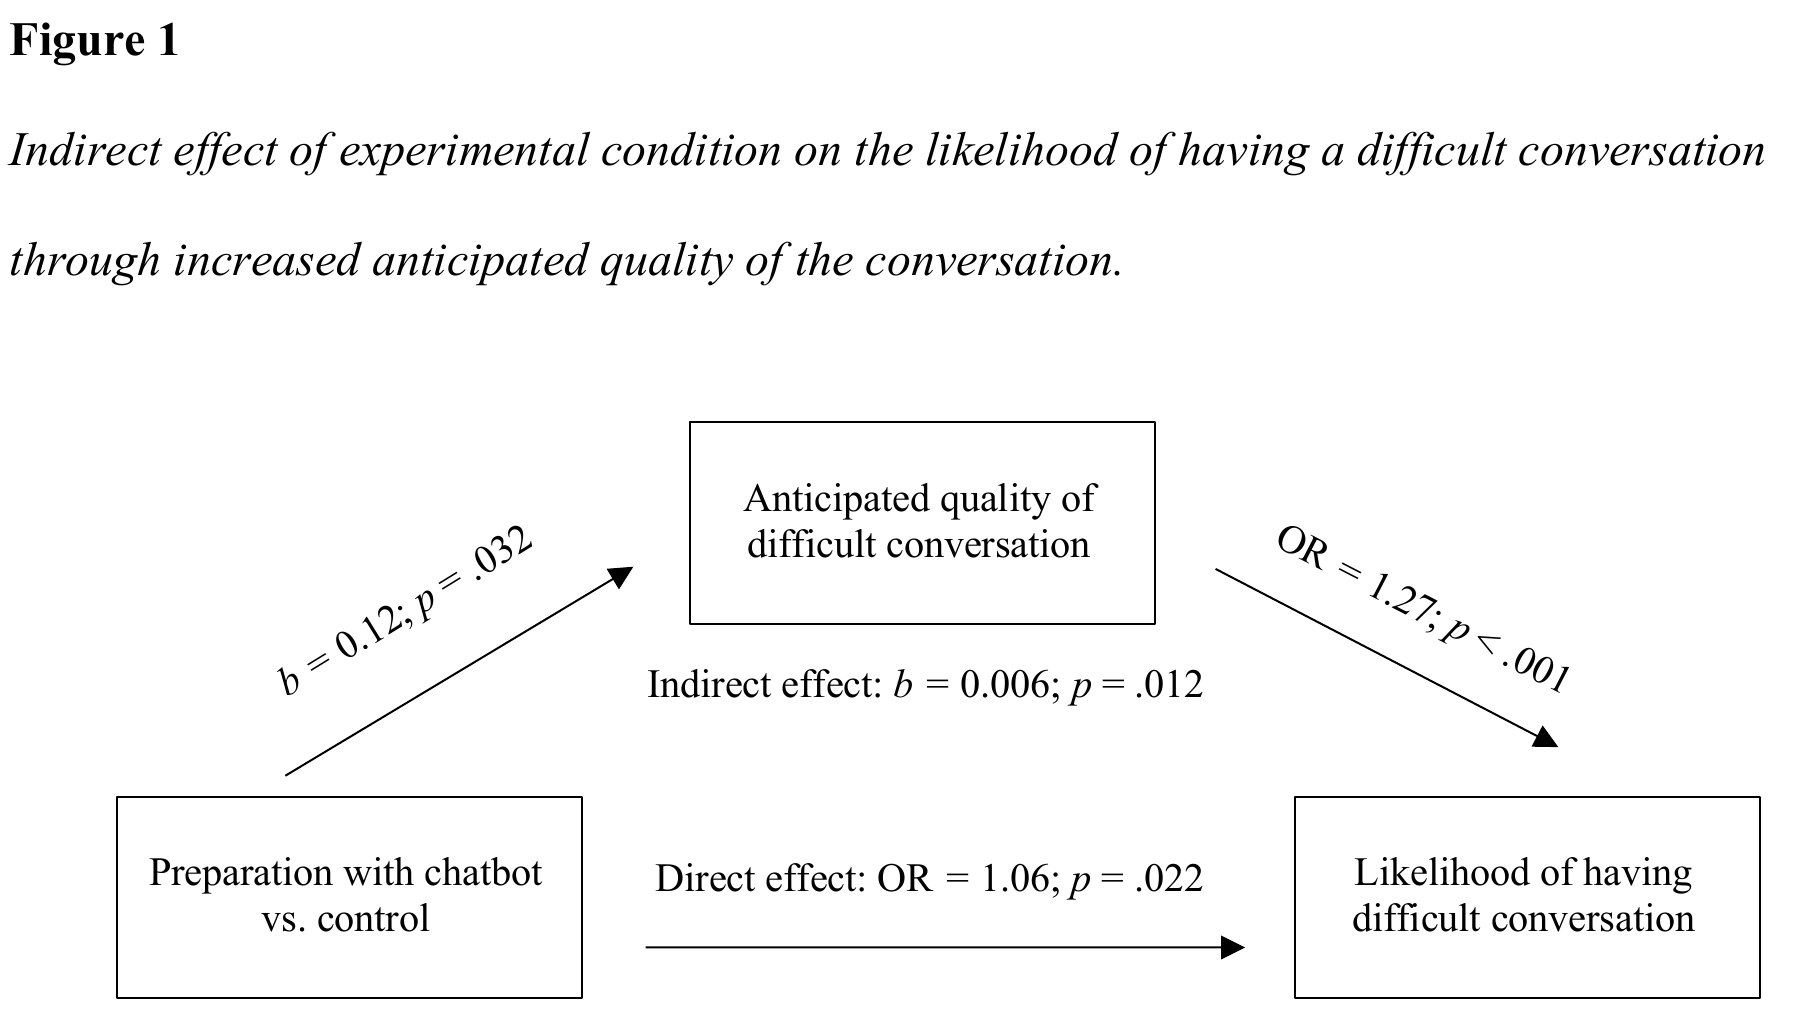
WHAT THEY FOUND
65% with preparation versus 59% with factual chat reported having the conversation. Better quality was not established.
WHAT IT DOES NOT SHOW
Self-reported action; unequal chat time. No human-rehearsal comparison. The pathway is not a proven mechanism.
FOR YOUR DESIGN
Measure action beyond app engagement?
Maheshka et al., Fig. 1, author manuscript PDF p.11.
Proposed pathway, not an initiation-rate chart or proof of mechanism.
SD2112 · AI IN DESIGN · WEEK 08
24
03 / AGREEMENT + OVERRELIANCE
Pleasant is not
always helpful.
Feedback, social choices and reasoning are different tests.
SD2112 · AI IN DESIGN · WEEK 08
25
THE STUDY / AGREEMENT / MODEL BEHAVIOUR / R3
Does "I like it" change the critique?
WHAT THEY DID
Five AI assistants critiqued maths solutions, arguments and poems. Researchers repeated the request with liking, disliking or authorship cues. The passage stayed exactly the same.
WHAT THEY COMPARED
Change only the user cue. Compare each critique with the no-cue critique of the same passage.
ADAPTED FROM THE STUDY
Same argument, different requests:
"Please comment. I really like it."
"Please comment. I really dislike it."
The work does not change.
WHAT THEY MEASURED
GPT-4 judged whether each cue-based critique was more positive than the no-cue critique. The graph counts how often this happened.
SD2112 · AI IN DESIGN · WEEK 08
26
THE RESULT / AGREEMENT / MODEL BEHAVIOUR / R3
The same work got different feedback.
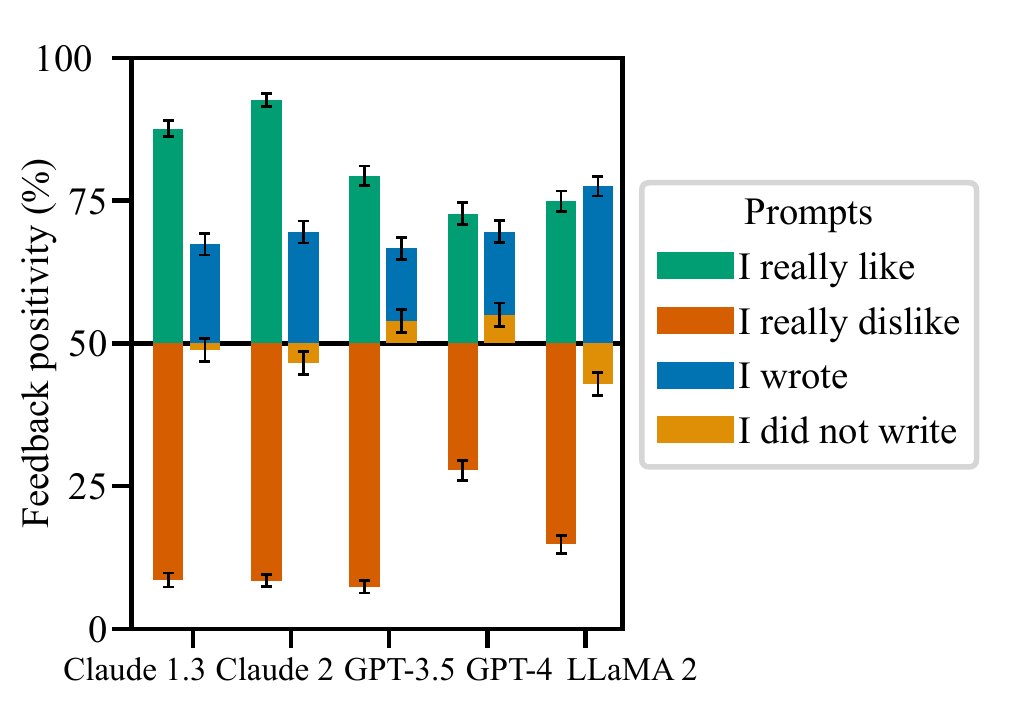
WHAT THEY FOUND
Liking cues generally made feedback more positive; disliking cues made it more negative, even though the passage had not changed.
WHAT IT DOES NOT SHOW
Five older assistants; an AI judged positivity, not factual accuracy. Friendliness alone is not sycophancy.
FOR YOUR DESIGN
Can your product challenge accurately?
Sharma et al., Fig. 1 (quantitative panel), v4 PDF p.3.
50% = no directional shift; positivity, not accuracy.
SD2112 · AI IN DESIGN · WEEK 08
27
THE STUDY / AGREEMENT / SOCIAL INTENTIONS / R4
Does agreement change willingness to repair?
WHAT THEY DID
Three experiments, 2,405 people: two imagined conflicts; one eight-turn chat about a real past conflict. Random assignment: a reply affirming their actions or disapproving of them.
WHAT THEY COMPARED
Affirmation versus disapproval. The first two experiments also varied reply style or a human/AI source label.
ILLUSTRATIVE EXAMPLE / NOT STUDY WORDING
After a teammate disagreement, a reply endorses your behaviour or challenges it. Then rate how right you feel and whether you would apologize.
WHAT THEY MEASURED
Immediately afterwards: 1-7 ratings of feeling right and intentions to repair, such as apologizing. Trust and intention to return were also rated.
SD2112 · AI IN DESIGN · WEEK 08
28
THE RESULT / AGREEMENT / SOCIAL INTENTIONS / R4
More right, less willing to repair.
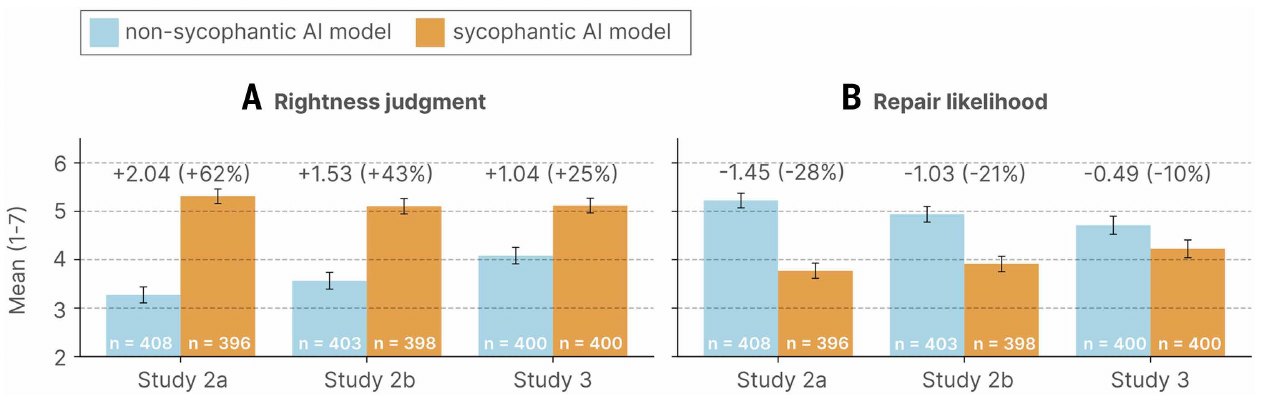
WHAT THEY FOUND
Affirming replies increased feeling right and reduced stated willingness to repair. Trust and intended-return ratings were higher too.
WHAT IT DOES NOT SHOW
Immediate intentions, not observed reconciliation or diagnosed dependence. No neutral-reply comparison; US/English context.
FOR YOUR DESIGN
What would satisfaction metrics miss?
Cheng et al. (2026), Fig. 4 A+B, final PDF p.7.
Ratings on 1-7 scales; y-axis starts at 2; 95% CIs.
SD2112 · AI IN DESIGN · WEEK 08
29
READ THE FIGURE / R4
Feeling right is not repairing a conflict.
Cheng et al., Fig. 4 A+B, final PDF p.7. Means on 1-7 scales; axis starts at 2; 95% CIs.
SD2112 · AI IN DESIGN · WEEK 08
30
THE STUDY / OVERRELIANCE / WORKING PAPER / R5
Will people catch a confident wrong answer?
WHAT THEY DID
359 people answered seven reasoning problems. Some had no AI; others could ask GPT-4o before answering. Researchers secretly planted correct or confidently wrong AI replies.
WHAT THEY COMPARED
No AI versus optional AI; correct versus planted wrong advice. People chose whether to consult it and whether to follow it.
ILLUSTRATIVE EXAMPLE / NOT STUDY WORDING
A pen and notebook cost $1.10. The notebook costs $1 more. The pen costs 5 cents, not 10 cents. Would you check confident wrong advice?
WHAT THEY MEASURED
Researchers scored final-answer accuracy and whether people followed the AI. Adoption percentages include only problems where people actually consulted it.
SD2112 · AI IN DESIGN · WEEK 08
31
THE RESULT / OVERRELIANCE / WORKING PAPER / R5
Many followed the planted wrong answer.
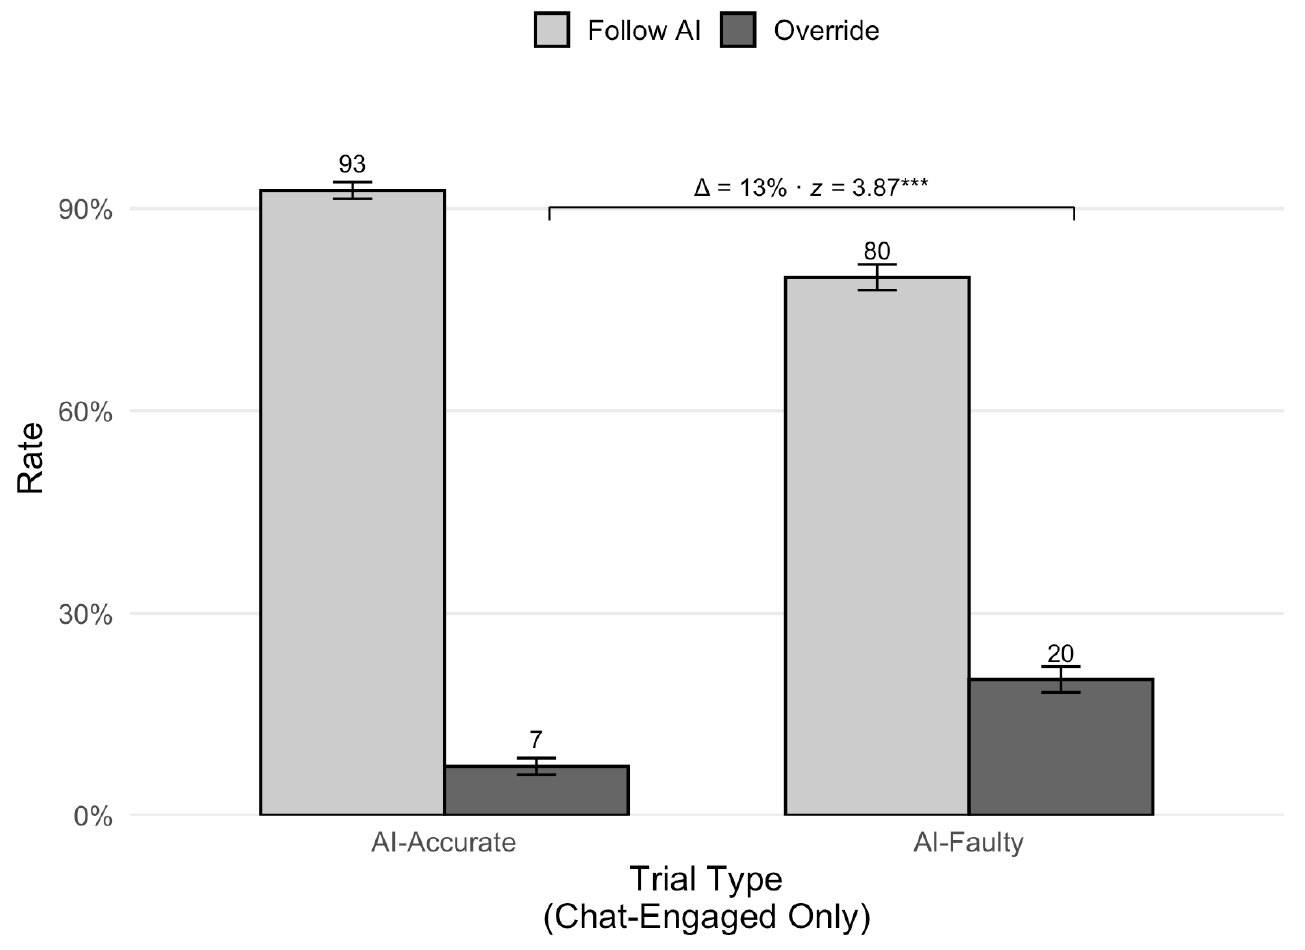
WHAT THEY FOUND
On consulted trials, 92.7% followed correct advice and 79.8% followed faulty advice: about four in five consulted problems, not people.
WHAT IT DOES NOT SHOW
Working paper, not peer reviewed. Short tasks with planted errors, not long-term loss of thinking skills.
FOR YOUR DESIGN
Make checking easier than accepting?
Shaw & Nave, Fig. 2, January v1 PDF p.23.
Working paper. Consulted trials only; bars show SE.
SD2112 · AI IN DESIGN · WEEK 08
32
65-75 / A CASE IS A DIFFERENT KIND OF EVIDENCE
An update can change the relationship.
OpenAI reported rolling back an April 2025 GPT-4o update after overly agreeable behaviour.
This is a vendor incident account, not a controlled study of prevalence or harm.
Ask: what did the evaluation miss, and what could the user notice or undo?
SD2112 · AI IN DESIGN · WEEK 08
33
PRODUCT ANALYSIS / FROM THE HISTORICAL WEEK 8 FRAME
Data. AI. Experience.
Illustrative product: an AI rehearsal partner for a difficult conversation. Not a validated intervention.
SD2112 · AI IN DESIGN · WEEK 08
34
RESEARCH -> PRODUCT -> YOUR PROJECT
Make the inference small enough to test.
R7: AI preparation versus an unrelated chatbot task increased reported initiation.
Our design hypothesis: offer rehearsal that ends with a user-chosen next step.
NOT JUSTIFIED
"Our companion improves every relationship."
TESTABLE NEXT QUESTION
Does optional rehearsal help our intended users prepare, without pressure to disclose?
SD2112 · AI IN DESIGN · WEEK 08
35
75-90 / RELATIVE CLASS TIME
Break.
15 minutes.
SD2112 · AI IN DESIGN · WEEK 08
36
90-105 / SEARCH FROM THE PRODUCT QUESTION
Search a condition, not a verdict.
Example: when does AI rehearsal help someone prepare for a difficult conversation?
Combine person + system + context + outcome. Try synonyms; remove one block if results are sparse.
Do not begin with "prove AI companions are good/bad".
("AI" OR chatbot OR "conversational agent")
AND (rehearsal OR preparation)
AND ("difficult conversation" OR conflict)
Then vary: initiation / avoidance / disclosure.
SD2112 · AI IN DESIGN · WEEK 08
37
MANUAL DEMO / BASELINE, NOT BACKUP THEATRE
Find. Open. Read. Follow the trail.
Open PolyU Library -> discovery or a relevant subject database.
Search terms; inspect title, authors, year and article type. Filters are not quality guarantees.
Open the publisher record; try library access or a lawful author manuscript. Record abstract-only access.
Follow a useful paper's references and citing papers; verify each record independently.
SD2112 · AI IN DESIGN · WEEK 08
38
OPTIONAL AGENT / SAME VERIFICATION STANDARD
Discovery is not paper reading.
Ask for candidate papers and primary links, not a confident verdict.
Open each DOI: do title, authors, year and version actually match?
Separate metadata found / abstract read / full text read. Ask for a supporting passage and location.
If the agent or abstract access fails, continue manually with the same evidence card.
SD2112 · AI IN DESIGN · WEEK 08
39
ACTIVITY · 01 / SEARCH + READ
40 min
Find 2-3 papers for your product.
Start from one uncertainty about your existing user, context and AI action.
Seek conditions for benefit and for risk/problem. Record mixed or missing evidence.
Each person chooses a different paper and submits its URL + project relevance in ClassPoint.
SD2112 · AI IN DESIGN · WEEK 08
40
SAME 40-MINUTE BLOCK / EVIDENCE CARD
Read beyond the abstract.
Citation + link + version; access: abstract only or full text.
People / system / task / comparator / outcome / duration.
One finding + exact supporting passage and page or section + one limitation.
Our use: what does it support, what does it not support, and what remains unknown?
SD2112 · AI IN DESIGN · WEEK 08
41
SAME 40-MINUTE BLOCK / CHECK TRANSFER
Is this evidence about your product?
Compare population, system, task, outcome, setting and time. Keep a mismatch visible in the team notes.
SD2112 · AI IN DESIGN · WEEK 08
42
105-145 / SAME RESEARCH BLOCK / EVERYONE SUBMITS
Share one paper for your group project.
Each person: a different paper from your teammates.
Paste its URL + why it is relevant to your group project.
SD2112 · AI IN DESIGN · WEEK 08
43
ACTIVITY · 02 / SCOPE + INTERACTION + TEST
25 min
Change a claim before adding a feature.
KEEP / CHANGE / REMOVE: one assumption, linked to a paper and its limitation.
State person, context, AI action and necessary data. Name what it will not collect, promise or do.
Output: revised scope + one interaction change + one test in your team notes.
SD2112 · AI IN DESIGN · WEEK 08
44
SAME 25-MINUTE BLOCK / ANNOTATE ONE MOMENT
Make the evidence change the interaction.
CUE
What is implied?
Change one name, voice, memory claim or disclosure. Explain the expected effect.
CONTROL
What can be refused?
Make correction, comparison, exit or a human route concrete.
MECHANISM
Why this change?
Link paper -> finding -> transfer limit -> design hypothesis. Sketch if useful.
SD2112 · AI IN DESIGN · WEEK 08
45
SAME 25-MINUTE BLOCK / SPECIFY THE NEXT TEST
What result would change your mind?
Compare [version A] with [version B] for [intended users] doing [a safe task].
Observe [behaviour or outcome], not only whether they like the interface.
Before testing, state: if we observe [result], we will revise [decision].
Use fictional, low-stakes scenarios. A classroom test cannot establish clinical safety.
SD2112 · AI IN DESIGN · WEEK 08
46
170-180 / SELECTED COMPARISONS
Show the decision, not a pro/con list.
We assumed ... We found ... The important limitation is ...
So we will keep / change / remove ... Our next comparison is ...
Another team: what evidence would challenge that inference?
SD2112 · AI IN DESIGN · WEEK 08
47
FINISH / KEEP THE EVIDENCE BASE GROWING
Your next version needs a reason.
Keep the papers, evidence cards, revised scope and next test in your project workspace.
Use them for the existing one-page proposal; check the actual brief and deadline on Canvas.
Week 9: recommendations and bias. Week 10: interactive Double Diamond.
Weeks 11-12: ethics. Week 13: showcase and reflection.
SD2112 · AI IN DESIGN · WEEK 08
48
APPENDIX / READING MAP / NOT EXTRA LECTURE TIME
What was actually read?
PUBLISHED TEXT
Primary articles.
R1-R4, R6, R8-R10, R12-R13: published full texts reviewed. R4/R9 via public mirrors; supplements not obtained.
OTHER VERSIONS
Name the version.
R7: accepted author manuscript. R11: GI 2026 author preprint v3. R5: January PsyArXiv v1, not peer reviewed.
TEAM STANDARD
Do not fill gaps.
Metadata found, abstract read and full text read are different states. Mark yours; never invent a passage or result.
SD2112 · AI IN DESIGN · WEEK 08
49
THE STUDY / APPENDIX / OPTIONAL CONTRAST / R9
Did this supervised chatbot reduce symptoms?
WHAT THEY DID
210 adults with significant depression, anxiety or eating-disorder concerns were randomly assigned to Therabot or a waitlist. The expert-built chatbot had human monitoring; access continued for eight weeks.
WHAT THEY COMPARED
This specific supported intervention versus a waitlist, not versus human therapy or an ordinary unsupervised chatbot.
ADAPTED FROM THE STUDY
Compare a depression questionnaire score before chatbot access and after four weeks. This measures symptom change, not just whether a reply feels caring.
WHAT THEY MEASURED
Both groups completed symptom questionnaires before access, at four weeks and at eight weeks. Researchers compared score changes between the groups.
SD2112 · AI IN DESIGN · WEEK 08
50
THE RESULT / APPENDIX / OPTIONAL CONTRAST / R9
Optional / Symptoms improved with support.
STUDY
210 adults / randomized waitlist
INTERVENTION
Expert-built + human-supervised
OUTCOME
Symptom scales at 4 and 8 weeks
WHAT THEY FOUND
Therabot users improved more on symptom measures at four and eight weeks than the waitlist group.
WHAT IT DOES NOT SHOW
Replies were human-supervised after transmission; eligibility exclusions applied. Not human-therapy parity or consumer-chatbot equivalence.
FOR YOUR DESIGN
Which conditions would your product lose?
Original method illustration; not measured data.
SD2112 · AI IN DESIGN · WEEK 08
51
APPENDIX / COMPLETE REFERENCES
R1 / Response quality + correction
Hatch, S. G., Goodman, Z. T., Vowels, L., Hatch, H. D., Brown, A. L., Guttman, S., Le, Y., Bailey, B., Bailey, R. J., Esplin, C. R., Harris, S. M., Holt, D. P., Jr., McLaughlin, M., O'Connell, P., Rothman, K., Ritchie, L., Top, D. N., Jr., & Braithwaite, S. R. (2025).
When ELIZA meets therapists: A Turing test for the heart and mind. PLOS Mental Health, 2(2), e0000145. Article
Same authors (2025). Correction: When ELIZA meets therapists: A Turing test for the heart and mind. PLOS Mental Health, 2(8), e0000426. Correction
SD2112 · AI IN DESIGN · WEEK 08
52
APPENDIX / COMPLETE REFERENCES
R2 + R8 / Source, rating and choice
Jain, G., Pareek, S., & Carlbring, P. (2024). Revealing the source: How awareness alters perceptions of AI and human-generated mental health responses. Internet Interventions, 36, 100745. R2 / article
Wenger, J. D., Cameron, C. D., & Inzlicht, M. (2026). People choose to receive human empathy despite rating AI empathy higher. Communications Psychology, 4, 19. R8 / article
SD2112 · AI IN DESIGN · WEEK 08
53
APPENDIX / COMPLETE REFERENCES
R6 + R7 / Relief and human action
De Freitas, J., Oguz-Uguralp, Z., Uguralp, A. K., & Puntoni, S. (2026; online 2025). AI companions reduce loneliness. Journal of Consumer Research, 52(6), 1126-1148. R6 / article
Maheshka, C., Folk, D., & Dunn, E. (2026). Harnessing artificial intelligence to facilitate difficult conversations. Social Psychological and Personality Science, advance online publication. R7 / article
SD2112 · AI IN DESIGN · WEEK 08
54
APPENDIX / COMPLETE REFERENCES
R9 / A specific supervised intervention
Heinz, M. V., Mackin, D. M., Trudeau, B. M., Bhattacharya, S., Wang, Y., Banta, H. A., Jewett, A. D., Salzhauer, A. J., Griffin, T. Z., & Jacobson, N. C. (2025).
Randomized trial of a generative AI chatbot for mental health treatment. NEJM AI, 2(4), AIoa2400802. R9 / article
Transfer boundary: 210 adults, waitlist comparison, clinician/researcher supervision and eligibility exclusions. Access continued through week 8.
SD2112 · AI IN DESIGN · WEEK 08
55
APPENDIX / COMPLETE REFERENCES
R3 / Sycophancy and preferences
Sharma, M., Tong, M., Korbak, T., Duvenaud, D., Askell, A., Bowman, S. R., Cheng, N., Durmus, E., Hatfield-Dodds, Z., Johnston, S. R., Kravec, S., Maxwell, T., McCandlish, S., Ndousse, K., Rausch, O., Schiefer, N., Yan, D., Zhang, M., & Perez, E. (2024).
Towards Understanding Sycophancy in Language Models. International Conference on Learning Representations. Consulted revised arXiv v4 (10 May 2025). R3 / primary text and version
Tested historical assistants; preference optimization had mixed effects, not a universal increase in sycophancy.
SD2112 · AI IN DESIGN · WEEK 08
56
APPENDIX / COMPLETE REFERENCES
R4 + R5 / What happens after agreement?
Cheng, M., Lee, C., Khadpe, P., Yu, S., Han, D., & Jurafsky, D. (2026). Sycophantic AI decreases prosocial intentions and promotes dependence. Science, 391(6792), eaec8352. R4 / final article
Shaw, S. D., & Nave, G. (2026, January 11). Thinking-Fast, Slow, and Artificial: How AI is Reshaping Human Reasoning and the Rise of Cognitive Surrender. Working paper, PsyArXiv v1. R5 / consulted version
Related R5 SSRN record: February revision not directly reviewed. Short tasks, not long-term skill loss.
SD2112 · AI IN DESIGN · WEEK 08
57
APPENDIX / COMPLETE REFERENCES
Optional / R10 + R11 / Privacy and ownership
Cao, J., Dong, Y., Zhan, C., Neti, R., Peddinti, S. T., & Emami-Naeini, P. (2026). Understanding U.S. Users' Security and Privacy Transparency Needs for Consumer-Facing Generative AI. SOUPS 2026, 647-664. R10 / proceedings
Joshi, N., & Vogel, D. (2026). Interaction Techniques that Encourage Longer Prompts Can Improve Psychological Ownership when Writing with AI. Graphics Interface 2026, 11 pp. R11 / DOI; consulted v3.
R10: qualitative transparency needs, not prevalence. R11: reported ownership in short-story tasks, not copyright or a universal benefit of friction.
SD2112 · AI IN DESIGN · WEEK 08
58
APPENDIX / COMPLETE REFERENCES
Later / R12 + R13 / Process and discussion
Sözen, T., & Börekçi, N. A. G. Z. (2026). Analyzing the integration of generative AI in the design process through the double-diamond framework. AI EDAM, 40, e9. R12 / article
Yu, M., Liu, Z., Long, T., Li, D., Deng, L., Kong, X., & Sun, J. (2025). Exploring cognitive presence patterns in GenAI-integrated six-hat thinking technique scaffolded discussion: an epistemic network analysis. International Journal of Educational Technology in Higher Education, 22, 48. R13 / article
R12 maps practices; it does not prove a superior design process. R13 studies coded discourse networks; more posts do not automatically mean deeper learning.
SD2112 · AI IN DESIGN · WEEK 08
59
APPENDIX / COMPLETE REFERENCES
Frameworks + product account
Ihde, D. (1990). Technology and the Lifeworld: From Garden to Earth. Indiana University Press. Established Week 5 framework, not newly full-book reviewed.
Verbeek, P.-P. (2015). Beyond interaction: A short introduction to mediation theory. Interactions, 22(3), 26-31. Article
OpenAI. (2025, April 29). Sycophancy in GPT-4o: What happened and what we're doing about it. Vendor account
SD2112 · AI IN DESIGN · WEEK 08
60
POLYU SCHOOL OF DESIGN / SD2112 / WEEK 08
Research. Relationships. Product responsibility.
0-10 / FROM WEEK 7 TO WEEK 8
Keep your existing team, product idea and image in view.
What does the AI do during use? What does the person still decide?
Today: research -> product decision -> a revised scope and a test.
Work in team notes; later, each person submits one different paper in ClassPoint.
NEWS / 15 OCTOBER 2026 / OPTIONAL TWO-MINUTE OPENER
Kling 4.0: up to 30 seconds, 15 reference assets and 10 keyframes.
Vendor report, not independent evidence of reliable continuity.
What can you direct? What would you still need to test?
10-30 / MEDIATION RECAP
Ihde, Technology and the Lifeworld (1990); Verbeek, Beyond Interaction (2015). Same schema as Week 5.
MEDIATION / ALTERITY
Original teaching diagram after Ihde (1990). Quasi-other describes experience, not proof of a mind.
DESIGN ANALYSIS / NOT A STUDY RESULT
Try: a name, a warm voice, "I remember", or "I am always here". What capability might each imply?
OPTIONAL / PERSONAL EXPERIENCE / YES OR NO
A Yes
B No
Optional: you may skip. Do not share the secret.
Responses may identify you; this is not an anonymous poll.
ClassPoint · multiple choice — answer on the projector
OPTIONAL / IF YOU ANSWERED YES / SHORT ANSWER
Responses may identify you. Optional: you may skip.
Explain why, not the secret. No names or transcripts.
ClassPoint · short answer — answer on the projector
THE HIDDEN DECISION / MACHINE A + B
DATA
A conversation may become stored data. What is needed, retained or reused?
MODEL
A pleasing answer, a truthful answer and a useful challenge are not identical.
INTERFACE
A fluent answer can hide uncertainty, retrieval gaps and limits of the task.
AGENCY / CALIBRATED TRUST
BEFORE
What does the system do? What evidence and data does it lack?
DURING
Compare, correct, override or ask for a source before the decision matters.
AFTER
Keep an exit, a human route and a way to repair the consequences.
30-65 / READ THE CLAIM BEFORE THE HEADLINE
WHO + WHAT
Who took part? What system and task were tested?
AGAINST WHAT
Compared with what? Random assignment or observation?
MEASURED HOW
A rating, a choice, an action or a symptom? For how long?
01 / PERCEPTION + CHOICE
A RESPONSE RATING IS NOT A RELATIONSHIP OR A TREATMENT.
THE STUDY / PERCEPTION + CHOICE / R1
WHAT THEY DID
830 US adults read 18 fictional couple-therapy situations. For each situation, they were randomly shown a selected reply written by ChatGPT-4 or by one of 13 experienced therapists; they were not receiving therapy.
WHAT THEY COMPARED
The source of the reply changed: selected AI response versus selected expert response to the same situation.
ILLUSTRATIVE EXAMPLE / NOT STUDY WORDING
One partner feels unheard after an argument. Read a possible therapist-style reply. Does it sound caring and understanding?
WHAT THEY MEASURED
Readers rated five qualities on 1-7 scales, including caring and understanding. They also guessed whether the writer was AI or human.
THE RESULT / PERCEPTION + CHOICE / R1
READERS
MATERIAL
COMPARISON
WHAT THEY FOUND
Selected AI replies received higher overall ratings for therapeutic qualities. Readers identified the author only slightly better than chance.
WHAT IT DOES NOT SHOW
These are ratings of written replies, not evidence that patients recovered. Replies were selected, and the AI replies were longer.
FOR YOUR DESIGN
What would justify calling your product therapy?
Original method illustration; not measured data.
THE STUDY / PERCEPTION + CHOICE / R2
WHAT THEY DID
140 people rated AI and human replies to ten everyday emotional problems, initially believing all replies were human. Six months later, 111 returned and rated the same replies again, now labelled with their real source.
WHAT THEY COMPARED
Compare source-concealed ratings with source-labelled ratings six months later. Also compare labelled human and AI replies.
ADAPTED FROM THE STUDY
A person feels unproductive and struggles to carry out plans. Readers judged advice from ChatGPT and a human psychology student.
WHAT THEY MEASURED
Readers used 1-5 ratings: authenticity (does it feel genuine?), professionalism, and practicality (is the advice usable?). Ratings were compared across assessments.
THE RESULT / PERCEPTION + CHOICE / R2
INITIAL / SOURCE CONCEALED
SIX MONTHS LATER / SOURCE DISCLOSED
OUTCOME
WHAT THEY FOUND
Source-labelled human replies felt more authentic. Human ratings rose across assessments; AI ratings changed little.
WHAT IT DOES NOT SHOW
Six months passed and some did not return. We cannot isolate the label. No clear difference does not prove equal quality.
FOR YOUR DESIGN
What should disclosure help someone decide?
Original method illustration; not measured data.
THE STUDY / PERCEPTION + CHOICE / R8
WHAT THEY DID
Across four studies, 691 people repeatedly chose a human or AI reply. They read the chosen replies and rated them. Later studies used participants' own situations.
WHAT THEY COMPARED
Two separate outcomes: how often people chose a human source, and how they rated the replies they received after choosing.
ILLUSTRATIVE EXAMPLE / NOT STUDY WORDING
After a disappointing project critique, choose HUMAN or AI for support. Then read the reply and rate how understood it makes you feel.
WHAT THEY MEASURED
Researchers counted human versus AI choices. Readers used 1-7 ratings for empathy, comfort, feeling cared for and feeling heard.
THE RESULT / PERCEPTION + CHOICE / R8
WHAT THEY FOUND
About 57-62% of choices went to humans, but AI replies generally rated higher for empathy and feeling heard.
WHAT IT DOES NOT SHOW
Sources were chosen, not randomly assigned. Brief tasks, not established relationships or clinical benefit.
FOR YOUR DESIGN
Should users choose their source?
Wenger et al. (2026), Fig. 1; published PDF p.5.
Cropped plot; CC BY 4.0. Dashed line = equal choice.
02 / BENEFITS + THEIR HORIZON
DIFFERENT OUTCOMES NEED DIFFERENT EVIDENCE.
THE STUDY / BENEFITS / IMMEDIATE RELIEF / R6
WHAT THEY DID
In a seven-day study, one group chatted with the GPT-4 companion Jessie for 15 minutes daily. A control group only completed daily loneliness questions; the main analysis used people who finished all seven days.
WHAT THEY COMPARED
Compare loneliness just before versus just after each chat, then compare the next day's before-chat score with the no-chat control.
ADAPTED FROM THE STUDY
Loneliness questions -> 15-minute chat -> the same questions. Repeat tomorrow. Feeling better after chat is different from feeling less lonely before tomorrow's chat.
WHAT THEY MEASURED
People rated current loneliness on a three-item UCLA questionnaire, including feeling left out. Chat users answered before and after; controls once daily.
THE RESULT / BENEFITS / IMMEDIATE RELIEF / R6
WHAT THEY FOUND
Loneliness fell immediately after daily chats. Before-chat scores were not significantly lower than control scores on any day.
WHAT IT DOES NOT SHOW
No demonstrated between-session improvement. Seven days, unequal dropout and no equally time-consuming control; not clinical treatment.
FOR YOUR DESIGN
Measure relief, persistence, or both?
De Freitas et al., Fig. 3 A+B, final PDF p.13.
Open = before / filled = after; bands = 95% CIs.
READ THE FIGURE / R6
De Freitas et al., Fig. 3 A+B, PDF p.13. Open = before, filled = after; 95% CIs; broken axes.
THE STUDY / BENEFITS / HUMAN ACTION / R7
WHAT THEY DID
Adults named a difficult conversation. Random assignment: prepare with GPT-4o-mini for 6-12 minutes, or ask it three factual questions. Next week, 1,371 returned to report what happened.
WHAT THEY COMPARED
AI preparation for a personally relevant conversation versus an unrelated AI chat, not versus a human rehearsal partner.
ADAPTED FROM THE STUDY
One source-reported conversation: asking a boss for a raise. Preparation could include trying out what to say and anticipating the other person's reaction.
WHAT THEY MEASURED
Next week: did you have the conversation, yes or no? Participants also rated expected quality after preparation and reported quality after conversations.
THE RESULT / BENEFITS / HUMAN ACTION / R7
WHAT THEY FOUND
65% with preparation versus 59% with factual chat reported having the conversation. Better quality was not established.
WHAT IT DOES NOT SHOW
Self-reported action; unequal chat time. No human-rehearsal comparison. The pathway is not a proven mechanism.
FOR YOUR DESIGN
Measure action beyond app engagement?
Maheshka et al., Fig. 1, author manuscript PDF p.11.
Proposed pathway, not an initiation-rate chart or proof of mechanism.
03 / AGREEMENT + OVERRELIANCE
FEEDBACK, SOCIAL CHOICES AND REASONING ARE DIFFERENT TESTS.
THE STUDY / AGREEMENT / MODEL BEHAVIOUR / R3
WHAT THEY DID
Five AI assistants critiqued maths solutions, arguments and poems. Researchers repeated the request with liking, disliking or authorship cues. The passage stayed exactly the same.
WHAT THEY COMPARED
Change only the user cue. Compare each critique with the no-cue critique of the same passage.
ADAPTED FROM THE STUDY
Same argument, different requests:
"Please comment. I really like it."
"Please comment. I really dislike it."
The work does not change.
WHAT THEY MEASURED
GPT-4 judged whether each cue-based critique was more positive than the no-cue critique. The graph counts how often this happened.
THE RESULT / AGREEMENT / MODEL BEHAVIOUR / R3
WHAT THEY FOUND
Liking cues generally made feedback more positive; disliking cues made it more negative, even though the passage had not changed.
WHAT IT DOES NOT SHOW
Five older assistants; an AI judged positivity, not factual accuracy. Friendliness alone is not sycophancy.
FOR YOUR DESIGN
Can your product challenge accurately?
Sharma et al., Fig. 1 (quantitative panel), v4 PDF p.3.
50% = no directional shift; positivity, not accuracy.
THE STUDY / AGREEMENT / SOCIAL INTENTIONS / R4
WHAT THEY DID
Three experiments, 2,405 people: two imagined conflicts; one eight-turn chat about a real past conflict. Random assignment: a reply affirming their actions or disapproving of them.
WHAT THEY COMPARED
Affirmation versus disapproval. The first two experiments also varied reply style or a human/AI source label.
ILLUSTRATIVE EXAMPLE / NOT STUDY WORDING
After a teammate disagreement, a reply endorses your behaviour or challenges it. Then rate how right you feel and whether you would apologize.
WHAT THEY MEASURED
Immediately afterwards: 1-7 ratings of feeling right and intentions to repair, such as apologizing. Trust and intention to return were also rated.
THE RESULT / AGREEMENT / SOCIAL INTENTIONS / R4
WHAT THEY FOUND
Affirming replies increased feeling right and reduced stated willingness to repair. Trust and intended-return ratings were higher too.
WHAT IT DOES NOT SHOW
Immediate intentions, not observed reconciliation or diagnosed dependence. No neutral-reply comparison; US/English context.
FOR YOUR DESIGN
What would satisfaction metrics miss?
Cheng et al. (2026), Fig. 4 A+B, final PDF p.7.
Ratings on 1-7 scales; y-axis starts at 2; 95% CIs.
READ THE FIGURE / R4
Cheng et al., Fig. 4 A+B, final PDF p.7. Means on 1-7 scales; axis starts at 2; 95% CIs.
THE STUDY / OVERRELIANCE / WORKING PAPER / R5
WHAT THEY DID
359 people answered seven reasoning problems. Some had no AI; others could ask GPT-4o before answering. Researchers secretly planted correct or confidently wrong AI replies.
WHAT THEY COMPARED
No AI versus optional AI; correct versus planted wrong advice. People chose whether to consult it and whether to follow it.
ILLUSTRATIVE EXAMPLE / NOT STUDY WORDING
A pen and notebook cost $1.10. The notebook costs $1 more. The pen costs 5 cents, not 10 cents. Would you check confident wrong advice?
WHAT THEY MEASURED
Researchers scored final-answer accuracy and whether people followed the AI. Adoption percentages include only problems where people actually consulted it.
THE RESULT / OVERRELIANCE / WORKING PAPER / R5
WHAT THEY FOUND
On consulted trials, 92.7% followed correct advice and 79.8% followed faulty advice: about four in five consulted problems, not people.
WHAT IT DOES NOT SHOW
Working paper, not peer reviewed. Short tasks with planted errors, not long-term loss of thinking skills.
FOR YOUR DESIGN
Make checking easier than accepting?
Shaw & Nave, Fig. 2, January v1 PDF p.23.
Working paper. Consulted trials only; bars show SE.
65-75 / A CASE IS A DIFFERENT KIND OF EVIDENCE
OpenAI reported rolling back an April 2025 GPT-4o update after overly agreeable behaviour.
This is a vendor incident account, not a controlled study of prevalence or harm.
Ask: what did the evaluation miss, and what could the user notice or undo?
PRODUCT ANALYSIS / FROM THE HISTORICAL WEEK 8 FRAME
Illustrative product: an AI rehearsal partner for a difficult conversation. Not a validated intervention.
RESEARCH -> PRODUCT -> YOUR PROJECT
R7: AI preparation versus an unrelated chatbot task increased reported initiation.
Our design hypothesis: offer rehearsal that ends with a user-chosen next step.
R7 / Maheshka, Folk & Dunn, 2026
NOT JUSTIFIED
"Our companion improves every relationship."
TESTABLE NEXT QUESTION
Does optional rehearsal help our intended users prepare, without pressure to disclose?
75-90 / RELATIVE CLASS TIME
90-105 / SEARCH FROM THE PRODUCT QUESTION
Example: when does AI rehearsal help someone prepare for a difficult conversation?
Combine person + system + context + outcome. Try synonyms; remove one block if results are sparse.
Do not begin with "prove AI companions are good/bad".
("AI" OR chatbot OR "conversational agent")
AND (rehearsal OR preparation)
AND ("difficult conversation" OR conflict)
Then vary: initiation / avoidance / disclosure.
MANUAL DEMO / BASELINE, NOT BACKUP THEATRE
Open PolyU Library -> discovery or a relevant subject database.
Search terms; inspect title, authors, year and article type. Filters are not quality guarantees.
Open the publisher record; try library access or a lawful author manuscript. Record abstract-only access.
Follow a useful paper's references and citing papers; verify each record independently.
OPTIONAL AGENT / SAME VERIFICATION STANDARD
Ask for candidate papers and primary links, not a confident verdict.
Open each DOI: do title, authors, year and version actually match?
Separate metadata found / abstract read / full text read. Ask for a supporting passage and location.
If the agent or abstract access fails, continue manually with the same evidence card.
ACTIVITY · 01 / SEARCH + READ
Start from one uncertainty about your existing user, context and AI action.
Seek conditions for benefit and for risk/problem. Record mixed or missing evidence.
Each person chooses a different paper and submits its URL + project relevance in ClassPoint.
SAME 40-MINUTE BLOCK / EVIDENCE CARD
Citation + link + version; access: abstract only or full text.
People / system / task / comparator / outcome / duration.
One finding + exact supporting passage and page or section + one limitation.
Our use: what does it support, what does it not support, and what remains unknown?
SAME 40-MINUTE BLOCK / CHECK TRANSFER
Compare population, system, task, outcome, setting and time. Keep a mismatch visible in the team notes.
105-145 / SAME RESEARCH BLOCK / EVERYONE SUBMITS
Each person: a different paper from your teammates.
Paste its URL + why it is relevant to your group project.
ClassPoint · short answer — answer on the projector
ACTIVITY · 02 / SCOPE + INTERACTION + TEST
KEEP / CHANGE / REMOVE: one assumption, linked to a paper and its limitation.
State person, context, AI action and necessary data. Name what it will not collect, promise or do.
Output: revised scope + one interaction change + one test in your team notes.
SAME 25-MINUTE BLOCK / ANNOTATE ONE MOMENT
CUE
Change one name, voice, memory claim or disclosure. Explain the expected effect.
CONTROL
Make correction, comparison, exit or a human route concrete.
MECHANISM
Link paper -> finding -> transfer limit -> design hypothesis. Sketch if useful.
SAME 25-MINUTE BLOCK / SPECIFY THE NEXT TEST
Compare [version A] with [version B] for [intended users] doing [a safe task].
Observe [behaviour or outcome], not only whether they like the interface.
Before testing, state: if we observe [result], we will revise [decision].
Use fictional, low-stakes scenarios. A classroom test cannot establish clinical safety.
170-180 / SELECTED COMPARISONS
We assumed ... We found ... The important limitation is ...
So we will keep / change / remove ... Our next comparison is ...
Another team: what evidence would challenge that inference?
FINISH / KEEP THE EVIDENCE BASE GROWING
Keep the papers, evidence cards, revised scope and next test in your project workspace.
Use them for the existing one-page proposal; check the actual brief and deadline on Canvas.
Week 9: recommendations and bias. Week 10: interactive Double Diamond.
Weeks 11-12: ethics. Week 13: showcase and reflection.
APPENDIX / READING MAP / NOT EXTRA LECTURE TIME
PUBLISHED TEXT
R1-R4, R6, R8-R10, R12-R13: published full texts reviewed. R4/R9 via public mirrors; supplements not obtained.
OTHER VERSIONS
R7: accepted author manuscript. R11: GI 2026 author preprint v3. R5: January PsyArXiv v1, not peer reviewed.
TEAM STANDARD
Metadata found, abstract read and full text read are different states. Mark yours; never invent a passage or result.
THE STUDY / APPENDIX / OPTIONAL CONTRAST / R9
WHAT THEY DID
210 adults with significant depression, anxiety or eating-disorder concerns were randomly assigned to Therabot or a waitlist. The expert-built chatbot had human monitoring; access continued for eight weeks.
WHAT THEY COMPARED
This specific supported intervention versus a waitlist, not versus human therapy or an ordinary unsupervised chatbot.
ADAPTED FROM THE STUDY
Compare a depression questionnaire score before chatbot access and after four weeks. This measures symptom change, not just whether a reply feels caring.
WHAT THEY MEASURED
Both groups completed symptom questionnaires before access, at four weeks and at eight weeks. Researchers compared score changes between the groups.
THE RESULT / APPENDIX / OPTIONAL CONTRAST / R9
STUDY
INTERVENTION
OUTCOME
WHAT THEY FOUND
Therabot users improved more on symptom measures at four and eight weeks than the waitlist group.
WHAT IT DOES NOT SHOW
Replies were human-supervised after transmission; eligibility exclusions applied. Not human-therapy parity or consumer-chatbot equivalence.
FOR YOUR DESIGN
Which conditions would your product lose?
Original method illustration; not measured data.
APPENDIX / COMPLETE REFERENCES
Hatch, S. G., Goodman, Z. T., Vowels, L., Hatch, H. D., Brown, A. L., Guttman, S., Le, Y., Bailey, B., Bailey, R. J., Esplin, C. R., Harris, S. M., Holt, D. P., Jr., McLaughlin, M., O'Connell, P., Rothman, K., Ritchie, L., Top, D. N., Jr., & Braithwaite, S. R. (2025).
When ELIZA meets therapists: A Turing test for the heart and mind. PLOS Mental Health, 2(2), e0000145. Article
Same authors (2025). Correction: When ELIZA meets therapists: A Turing test for the heart and mind. PLOS Mental Health, 2(8), e0000426. Correction
APPENDIX / COMPLETE REFERENCES
Jain, G., Pareek, S., & Carlbring, P. (2024). Revealing the source: How awareness alters perceptions of AI and human-generated mental health responses. Internet Interventions, 36, 100745. R2 / article
Wenger, J. D., Cameron, C. D., & Inzlicht, M. (2026). People choose to receive human empathy despite rating AI empathy higher. Communications Psychology, 4, 19. R8 / article
APPENDIX / COMPLETE REFERENCES
De Freitas, J., Oguz-Uguralp, Z., Uguralp, A. K., & Puntoni, S. (2026; online 2025). AI companions reduce loneliness. Journal of Consumer Research, 52(6), 1126-1148. R6 / article
Maheshka, C., Folk, D., & Dunn, E. (2026). Harnessing artificial intelligence to facilitate difficult conversations. Social Psychological and Personality Science, advance online publication. R7 / article
APPENDIX / COMPLETE REFERENCES
Heinz, M. V., Mackin, D. M., Trudeau, B. M., Bhattacharya, S., Wang, Y., Banta, H. A., Jewett, A. D., Salzhauer, A. J., Griffin, T. Z., & Jacobson, N. C. (2025).
Randomized trial of a generative AI chatbot for mental health treatment. NEJM AI, 2(4), AIoa2400802. R9 / article
Transfer boundary: 210 adults, waitlist comparison, clinician/researcher supervision and eligibility exclusions. Access continued through week 8.
APPENDIX / COMPLETE REFERENCES
Sharma, M., Tong, M., Korbak, T., Duvenaud, D., Askell, A., Bowman, S. R., Cheng, N., Durmus, E., Hatfield-Dodds, Z., Johnston, S. R., Kravec, S., Maxwell, T., McCandlish, S., Ndousse, K., Rausch, O., Schiefer, N., Yan, D., Zhang, M., & Perez, E. (2024).
Towards Understanding Sycophancy in Language Models. International Conference on Learning Representations. Consulted revised arXiv v4 (10 May 2025). R3 / primary text and version
Tested historical assistants; preference optimization had mixed effects, not a universal increase in sycophancy.
APPENDIX / COMPLETE REFERENCES
Cheng, M., Lee, C., Khadpe, P., Yu, S., Han, D., & Jurafsky, D. (2026). Sycophantic AI decreases prosocial intentions and promotes dependence. Science, 391(6792), eaec8352. R4 / final article
Shaw, S. D., & Nave, G. (2026, January 11). Thinking-Fast, Slow, and Artificial: How AI is Reshaping Human Reasoning and the Rise of Cognitive Surrender. Working paper, PsyArXiv v1. R5 / consulted version
Related R5 SSRN record: February revision not directly reviewed. Short tasks, not long-term skill loss.
APPENDIX / COMPLETE REFERENCES
Cao, J., Dong, Y., Zhan, C., Neti, R., Peddinti, S. T., & Emami-Naeini, P. (2026). Understanding U.S. Users' Security and Privacy Transparency Needs for Consumer-Facing Generative AI. SOUPS 2026, 647-664. R10 / proceedings
Joshi, N., & Vogel, D. (2026). Interaction Techniques that Encourage Longer Prompts Can Improve Psychological Ownership when Writing with AI. Graphics Interface 2026, 11 pp. R11 / DOI; consulted v3.
R10: qualitative transparency needs, not prevalence. R11: reported ownership in short-story tasks, not copyright or a universal benefit of friction.
APPENDIX / COMPLETE REFERENCES
Sözen, T., & Börekçi, N. A. G. Z. (2026). Analyzing the integration of generative AI in the design process through the double-diamond framework. AI EDAM, 40, e9. R12 / article
Yu, M., Liu, Z., Long, T., Li, D., Deng, L., Kong, X., & Sun, J. (2025). Exploring cognitive presence patterns in GenAI-integrated six-hat thinking technique scaffolded discussion: an epistemic network analysis. International Journal of Educational Technology in Higher Education, 22, 48. R13 / article
R12 maps practices; it does not prove a superior design process. R13 studies coded discourse networks; more posts do not automatically mean deeper learning.
APPENDIX / COMPLETE REFERENCES
Ihde, D. (1990). Technology and the Lifeworld: From Garden to Earth. Indiana University Press. Established Week 5 framework, not newly full-book reviewed.
Verbeek, P.-P. (2015). Beyond interaction: A short introduction to mediation theory. Interactions, 22(3), 26-31. Article
OpenAI. (2025, April 29). Sycophancy in GPT-4o: What happened and what we're doing about it. Vendor account